Works
AI-Powered Interview Assistant
Developed and deployed an internally adopted interview assessment tool using prompt engineering and LangChain to extract candidate skills, generate targeted questions, and evaluate responses, improving assessment consistency across hiring panels.
LangChain • Prompt Engineering • NLP • TCS Research

PennCloud - Distributed Cloud Platform
Architected and implemented a fault-tolerant distributed cloud system featuring a complete RFC 2822-compliant SMTP server, webmail interface with inbox/compose/reply functionality, and admin console with real-time multi-server monitoring. Designed email storage schema using row-based KV patterns and implemented MX record lookup for external email relay. System supports quorum-based Paxos consensus with automatic failover across 4+ backend servers.
C++ • gRPC • SMTP • WebSockets • Paxos Consensus • Distributed Systems
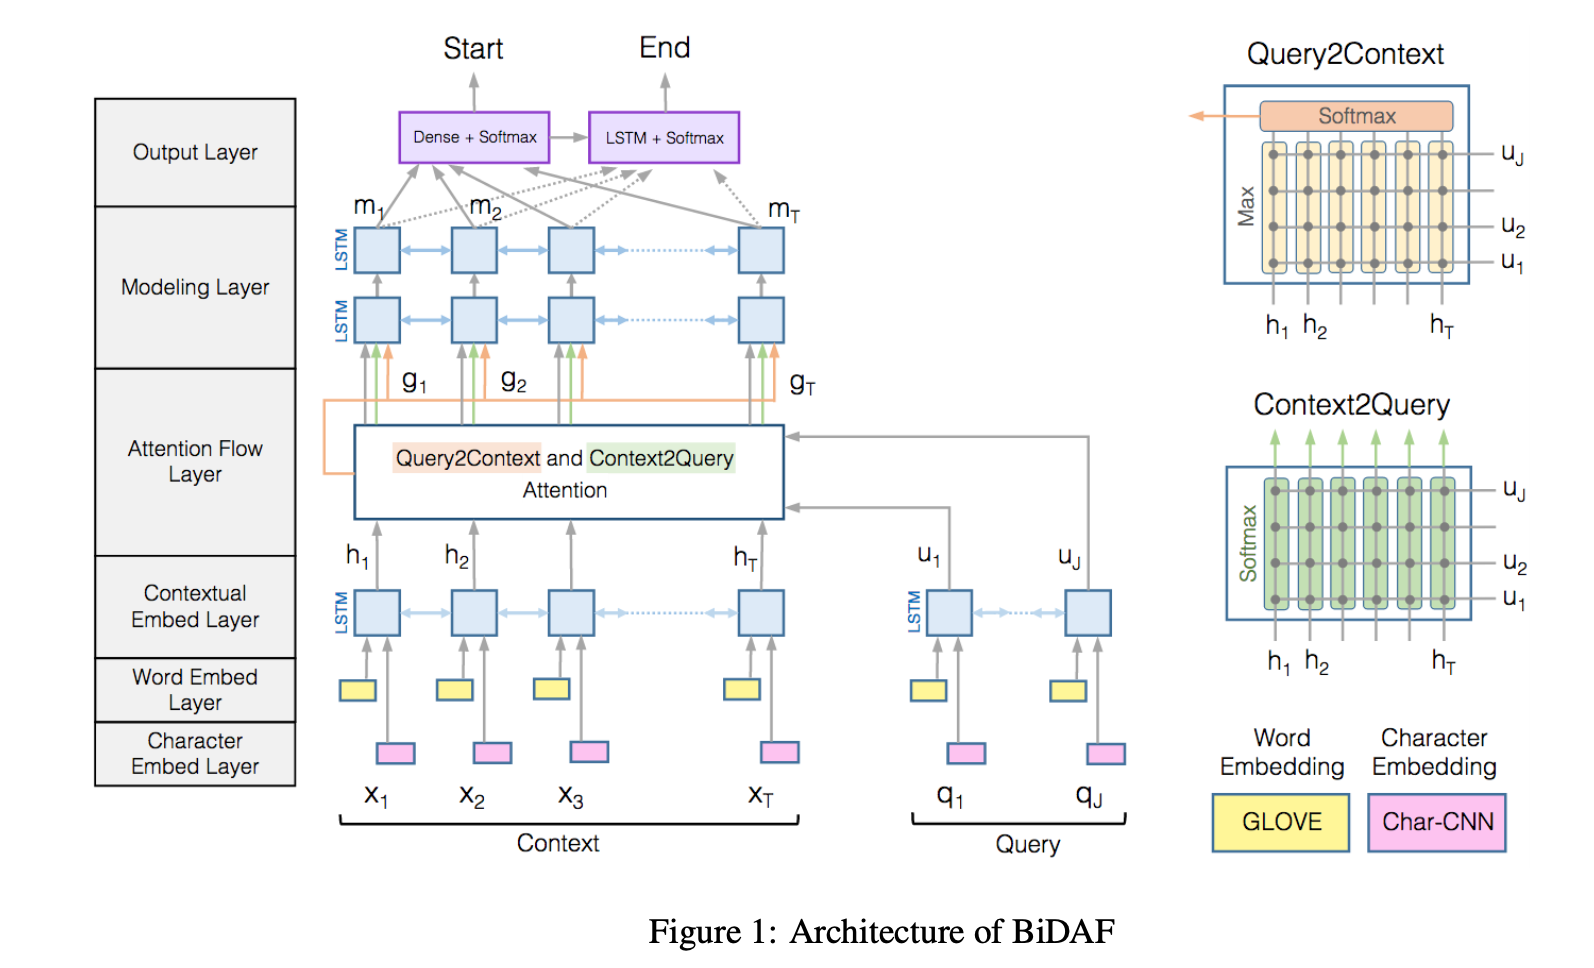
BiDAF Question Answering System
Reimplemented BiDAF network from scratch, achieving near state-of-the-art performance with optimized computational efficiency using 2.6M parameters. Demonstrated deep understanding of bi-directional attention mechanisms and hierarchical context modeling.
PyTorch • BiLSTM • Attention Mechanisms • NLP • SQuAD Dataset

Sherlock Bot
Built a conversational AI chatbot trained on BBC Sherlock scripts to generate character-specific dialogue using fine-tuned transformer models. Implemented context-aware response generation with Hugging Face Transformers, creating a bot that mimics Sherlock Holmes' distinctive speaking style and personality. Trained on dialogue data with character attribution for authentic character voice.
Python • Transformers • GPT-2 • NLP • Dialogue Generation • Character AI
Research Systems
MuRFE - Multi-valued Relation Extraction Pipeline
Collaborators: Pratik Saini, Bhavya Jain, Chayan Sarkar, Tapas Nayak
Built a complete pipeline for multi-valued relation extraction combining LLM-based synthetic data generation with supervised learning. Implemented advanced prompting strategies with Llama-3.3-70B to generate 3,000+ high-quality training samples across 8 relation types. Designed and trained sequence tagging models with pointer networks, achieving competitive performance against SOTA baselines (PRGC, BiRTE, TDEER). Created comprehensive benchmarking framework with evaluation scripts for relation extraction tasks where single subjects can have multiple object entities.
Python • PyTorch • Llama-3.3-70B • Sequence Tagging • Pointer Networks • Dataset Creation

Mental Health Evidence Extraction System
Collaborators: Sudeshna Jana, Manjira Sinha, Tirthankar Dasgupta (TCS Research)
Developed a production-ready NLP pipeline for extracting mental health evidence from social media timelines. Built custom RoBERTa fine-tuning pipeline for token-level classification of adaptive and maladaptive self-state evidence, achieving 60.2% recall. Implemented retrieval-augmented DeepSeek-7B model for well-being score prediction and created Random Forest baseline with sentence embeddings. System ranked 2nd in CLPsych 2025 shared task with 92.3% F1 on classification and 48% average score on entity extraction across 6 evidence types.
Python • RoBERTa • DeepSeek-7B • RAG • Random Forest • Mental Health NLP